
Loading
3366 Members
 Join Permit's Slack
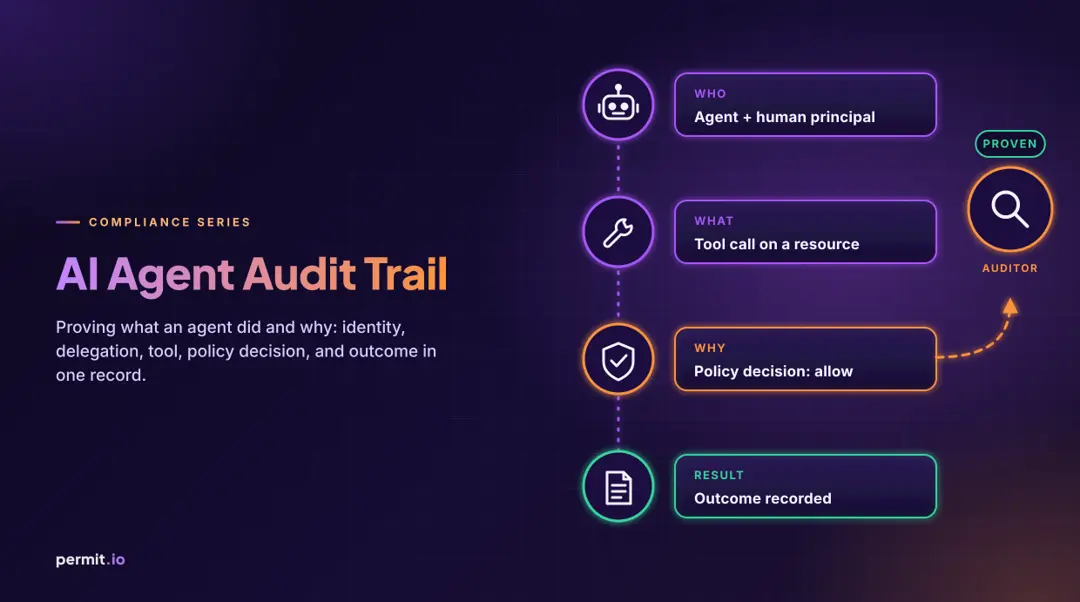
An AI agent audit trail proves what an agent did and why. You build it with authorization decision records that bind agent identity, the human principal or delegation chain, tool and resource, policy version, allow/deny with reason, any HITL approval, timestamps and correlation IDs, and preferably the outcome of the side effect. For background on how AI agent permissions differ from user permissions and why that matters for audit, start there. Tool traces alone are not enough.
An LLM trace can tell you what the model said. A tool trace can tell you what function was called. An authorization record tells you whether that action was permitted under the policy in force at that moment, for that agent, acting for that user, against that resource. That is the evidence auditors care about. For the general authorization-log product pattern, see also audit logs.
When an agent acts for a person, the record also needs the delegation chain. We cover that in human to agent delegation audit trails. For the control mapping auditors use, see the SOC 2 CC6.1 access control checklist for AI agents.
Tool traces are usually operational telemetry, not control evidence. A framework may log the prompt, model response, selected tool, arguments, latency, tokens, and errors. Useful for debugging. Not enough to prove access control.
For audit, the questions are: Who or what was authorized? On whose behalf? Under which policy? Against which resource? Allow or deny, and why? Was approval required? Was the side effect completed? Can we reproduce the decision later?
Telemetry explains model behavior. AuthZ evidence explains control enforcement. For more on that distinction, see Why Was This Allowed?.
Auditors sample evidence around access, change, monitoring, and incident response. For AI agents they ask the same control questions they already ask for humans and services, with a new actor type.
For SOC 2, that usually maps to logical access and system operations conversations around CC6 and CC7 in the AICPA Trust Services Criteria. For ISO 27001, expect similar questions around access management and logging, including Annex A.8.15. Overview: ISO/IEC 27001. For AI management systems specifically, see our ISO 42001 certification guide. For high-risk AI systems under European regulation, see the EU AI Act logging requirements breakdown.
They may pick a sensitive action and ask for the initiator, any approval, the policy that allowed it, evidence that denies are also logged, how agents are kept from exceeding permissions, how logs are protected and retained, and how you investigate anomalies.
"Our agent framework logs tool calls" proves execution, not authorization. A better answer: every tool call crosses a policy decision point, and we retain an AI agent audit trail with policy version, principal, agent, resource, action, reason, approval, timestamp, and correlation IDs.
Treat each agent action as an audit envelope. Capture at least:
The exact schema can vary. The envelope should let an auditor reconstruct both the control decision and the resulting action. Explainable deny logs prove the control is active. See Explainable Deny. For the field-by-field schema, see our guide to AI agent audit logs. For financial services teams, the same audit envelope can support DORA evidence and NIST-aligned control mapping. See DORA vs NIST access control.
AI agent logging for authorization belongs at the authorization boundary, not inside the model. Prefer the PDP (policy decision point) or an MCP gateway that enforces authorization before a tool executes. That is the moment intent becomes a possible side effect. If you log only after the tool runs, you missed the control point. For the architectural pattern behind enforcement and decision separation, see PEP vs PDP. The broader picture, covering real-time authorization enforcement from policy sync to audit logs, shows how these pieces connect.
Agents may call many tools quickly. You do not want every control to depend on best-effort application code or prompt instructions. You want a real authorization checkpoint at every sensitive tool-call boundary, with joinable correlation to the tool trace and the final system change.
If you are moving from broad agent permissions toward scoped models, also see Authorization Models to Least-Privilege Evidence.
When a policy requires a human to approve an agent action, the approval is part of the authorization evidence, not a side conversation in Slack. Record the approval ID, who approved or rejected, when, and which request it applied to, and link it to the same trace ID as the tool call. An auditor sampling a sensitive action should see: policy said approval required, this person approved at this time, then the side effect ran. For designing the approval flows themselves, see human-in-the-loop for AI agents.
Replaying does not mean re-running the model with a new temperature. It means reconstructing the decision: same principal, agent, tool, resource, policy version, attributes, approval state, and outcome. Immutable, correlated records make that possible. Prompt text may be stored under a separate privacy and retention model; the authorization envelope is what proves control.
Start from the authorization envelope for each sensitive tool call, then join it to the tool trace and the downstream system change with a shared correlation ID. That is how you audit what happened and why it was allowed.
No. They show execution and model behavior. Auditors also need proof of the access decision: who or what was authorized, under which policy, against which resource, and whether approval was required.
They help for authentication and token issuance. They usually do not prove each downstream agent action, policy version, resource context, or allow/deny reason. IdP logs are necessary. They are not a complete AI agent audit trail.
Yes, if you retained the authorization inputs and policy version with the decision. Replay here means reconstructing the control decision, not regenerating the LLM response.
Separate the model's reasoning from the access decision. The prompt and trace explain what the agent tried to do. The authorization record explains why it was allowed: the agent identity, the human it acted for, the policy version, the input attributes and the allow or deny reason. Store both under one correlation ID and you can answer "why did the agent do this" with evidence, not a guess about model intent.
Auth0 logs authentication events, such as logins and token issuance, for the agent's own identity. Those logs show that an agent got a token. Unless you add authorization logging at the tool layer, they do not show each tool call it made with that token, the resource it touched, or the policy that allowed it. Give the agent its own identity rather than letting it inherit the user's permissions, then log an authorization decision at every tool call. That decision log is the AI agent audit trail. Auth0 logs sit next to it as the authentication record.
Look for a gateway that sits in front of MCP servers, evaluates policy before the tool runs, and emits audit events that include agent identity, human principal, tool, resource, decision, and correlation IDs. Logging after the fact in the agent framework is not the same as enforcement-time logging.
If your compliance and engineering teams are defining this control model now, Permit can help map agent tool calls to policy, approvals, delegated access, and audit evidence. Start with Permit for compliance teams.
Co-Founder / CEO at Permit.io